Technical leads
See what automated work is changing across projects: objectives, task state, checks and approvals.
Dashboard Examples · Real build
A working front end for supervising AI coding agents: live status, approvals for risky steps and an audit trail. We built it in Claude Code with the AI Dashboard Mission Vault, and the live demo runs on simulated agents.
Built with the AI Dashboard Mission Vault and Claude CodeNov 2026Fictional sample data
$97, one-time: 75 mission blueprints, 7 Claude Code prompts and 4 brief templates to build your own dashboard. This example’s code isn’t included.
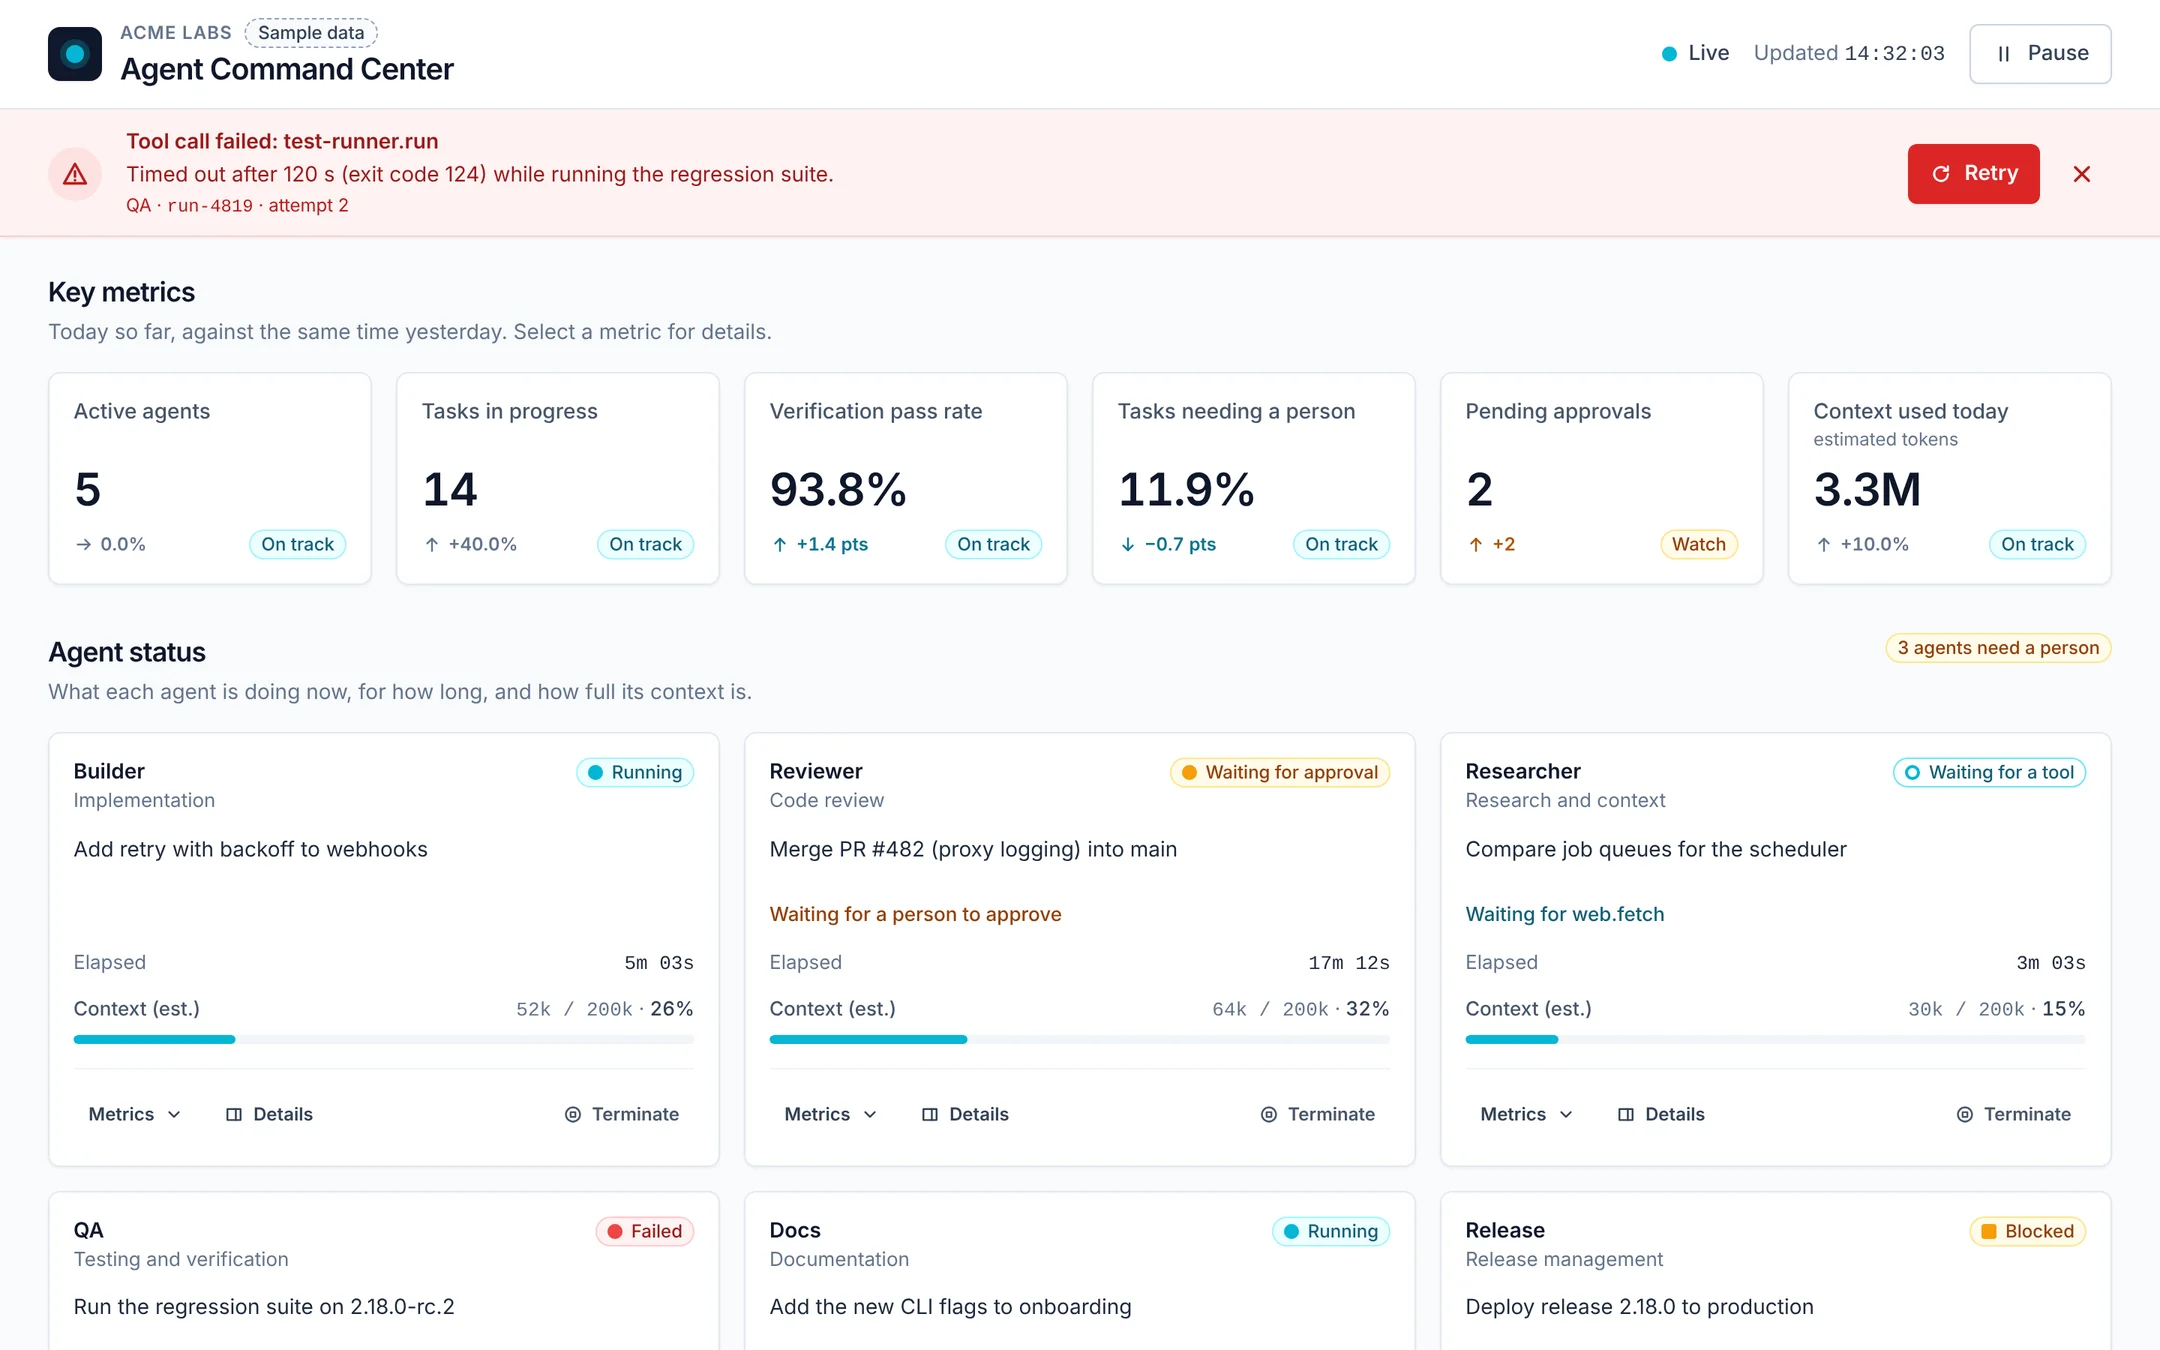
Real screenshots of the build, taken from the live demo.
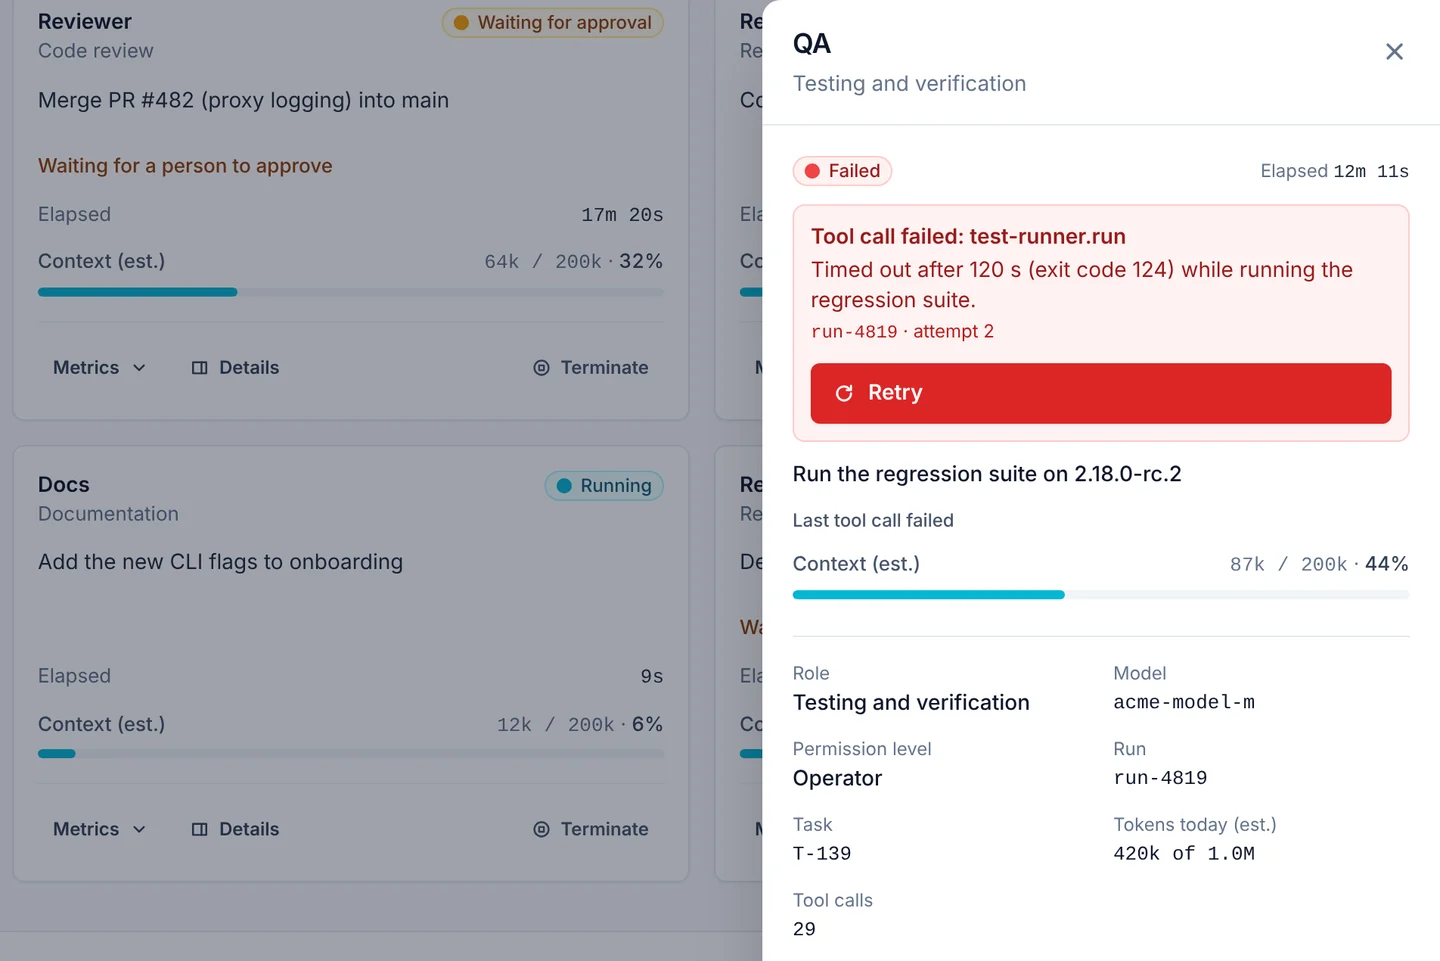
QA’s details: the failed tool call with Retry at the top, then its task, context use, model, permission level and estimated tokens today. Every agent, task and KPI opens like this.
Tap the screenshot to see it full size.
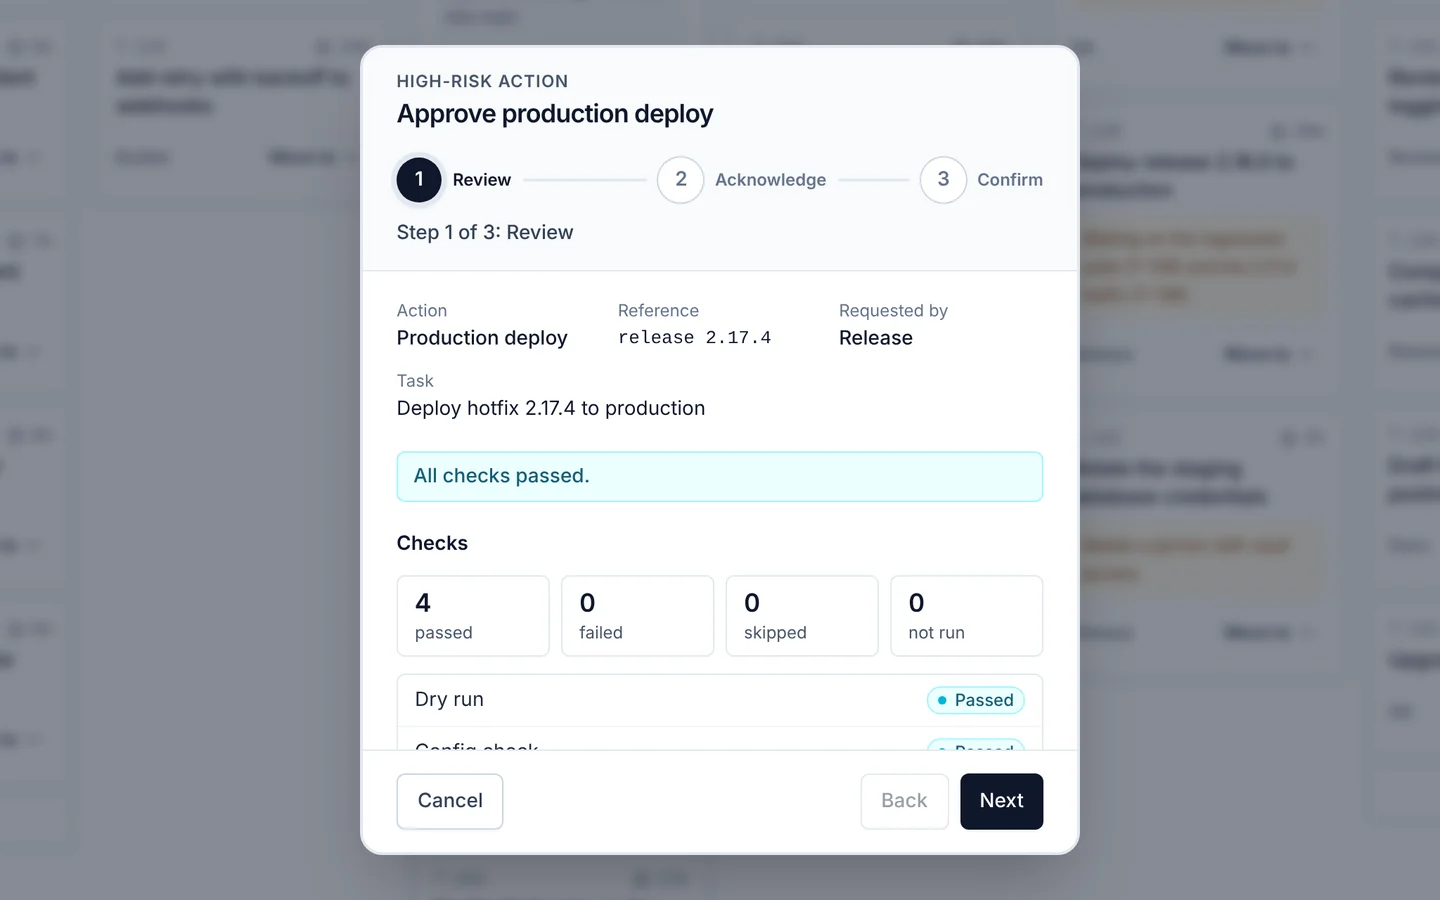
Merges to main and production deploys take three steps: review the checks, acknowledge the risk, then confirm. This one is the 2.17.4 hotfix.
Tap the screenshot to see it full size.
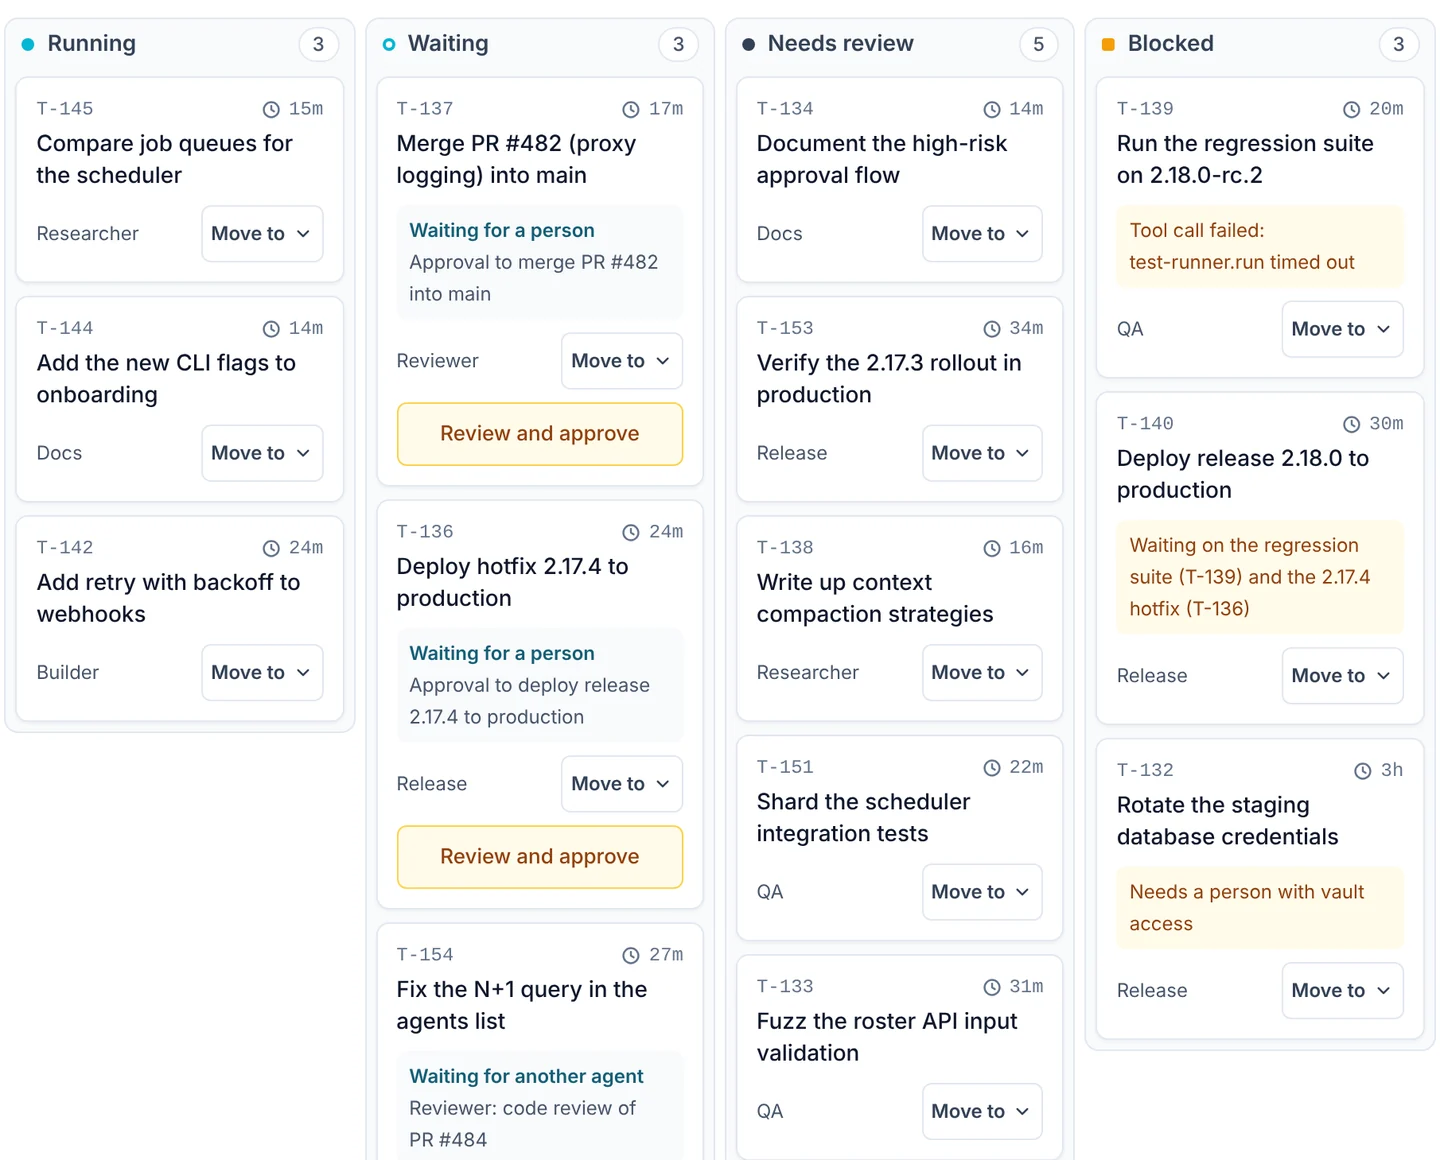
Waiting and blocked cards say why: an approval, a failed tool call, another task or a person with access.
Tap the screenshot to see it full size.
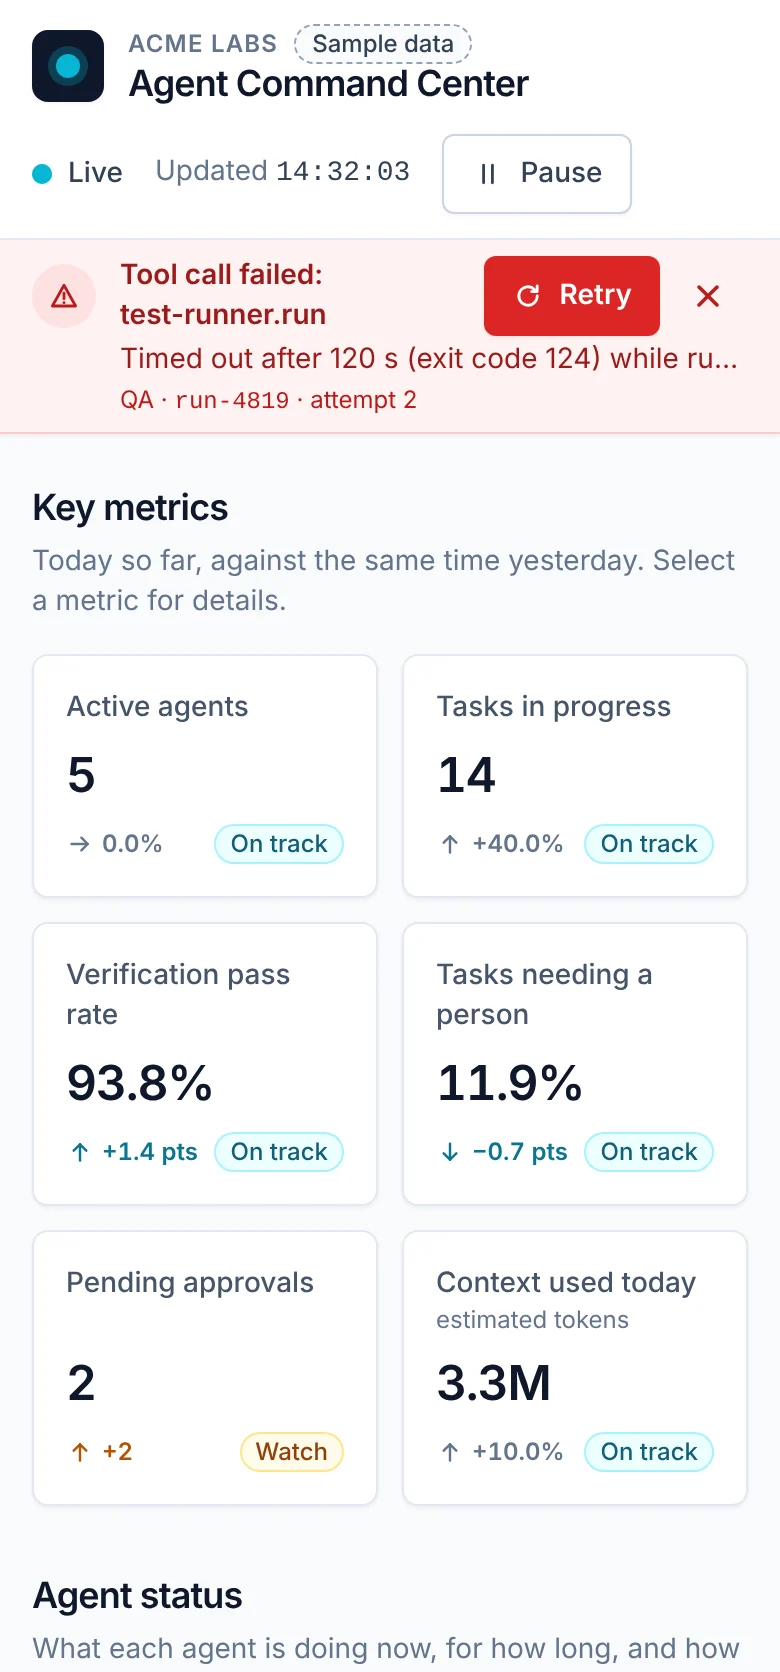 (opens the full-size screenshot in a new tab)
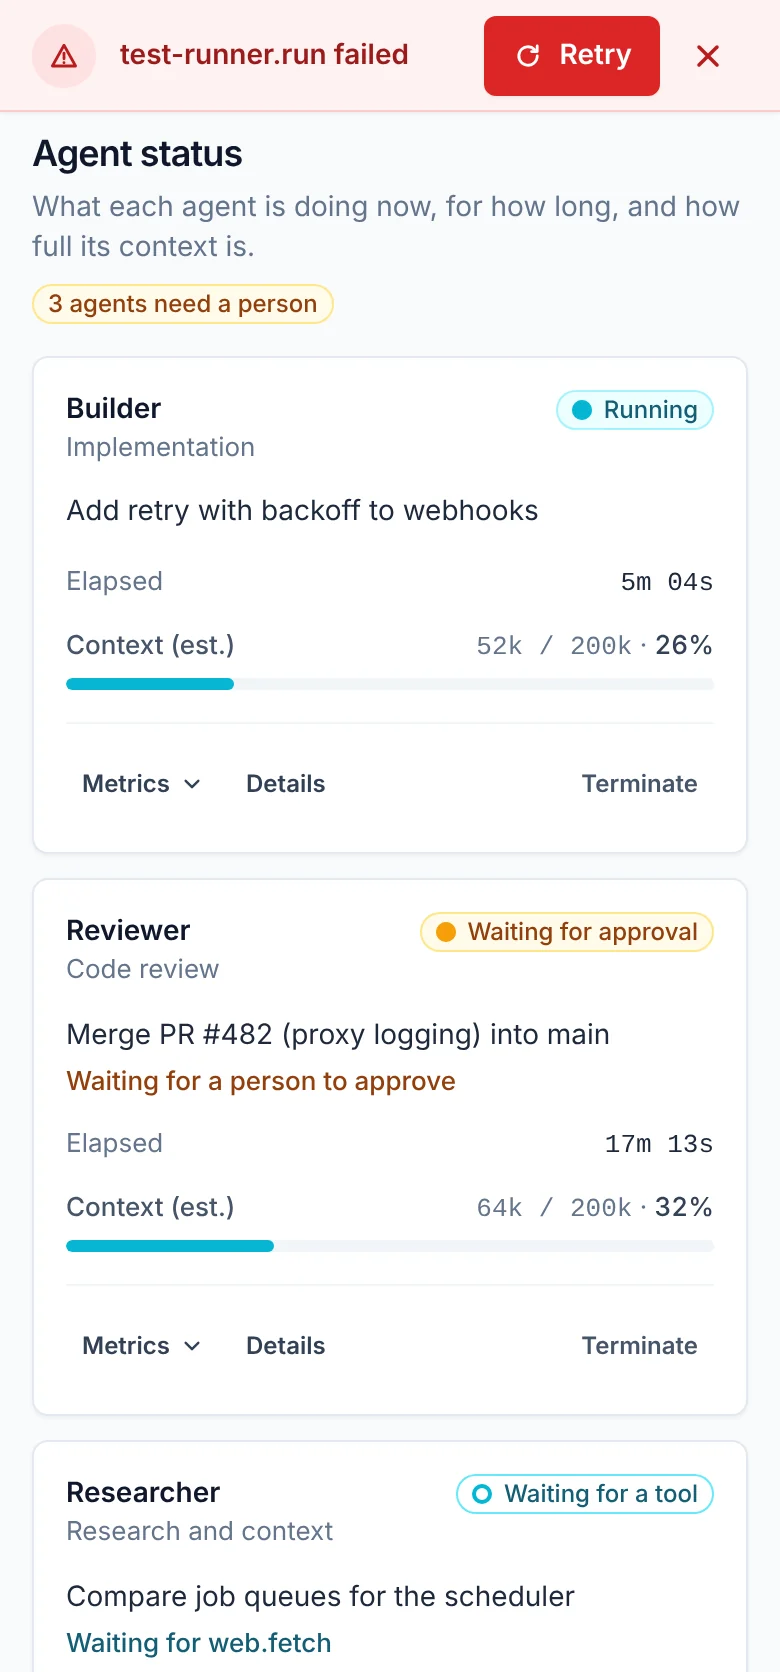 (opens the full-size screenshot in a new tab)
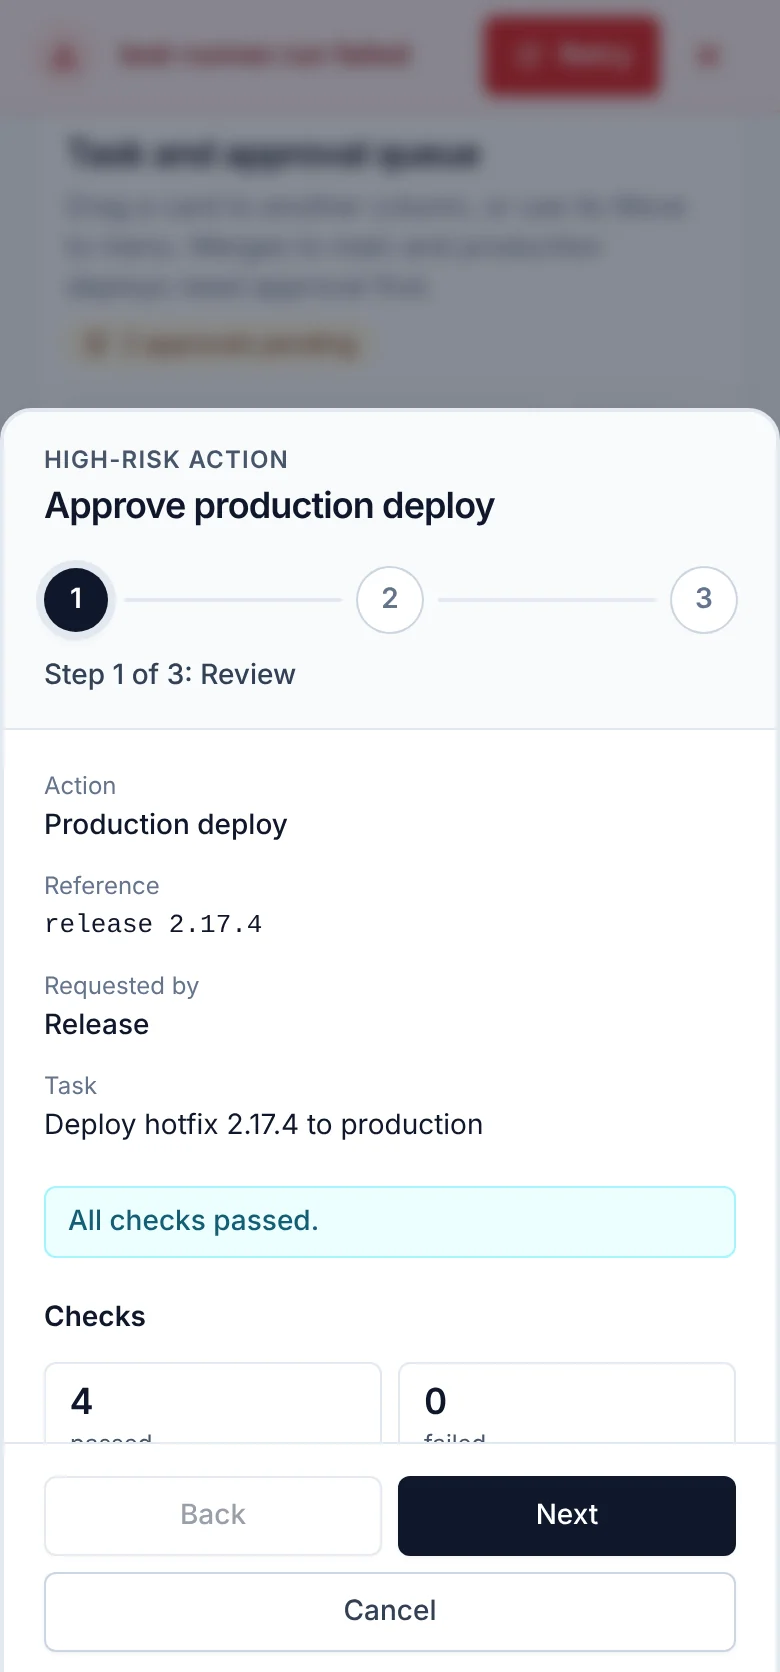 (opens the full-size screenshot in a new tab)
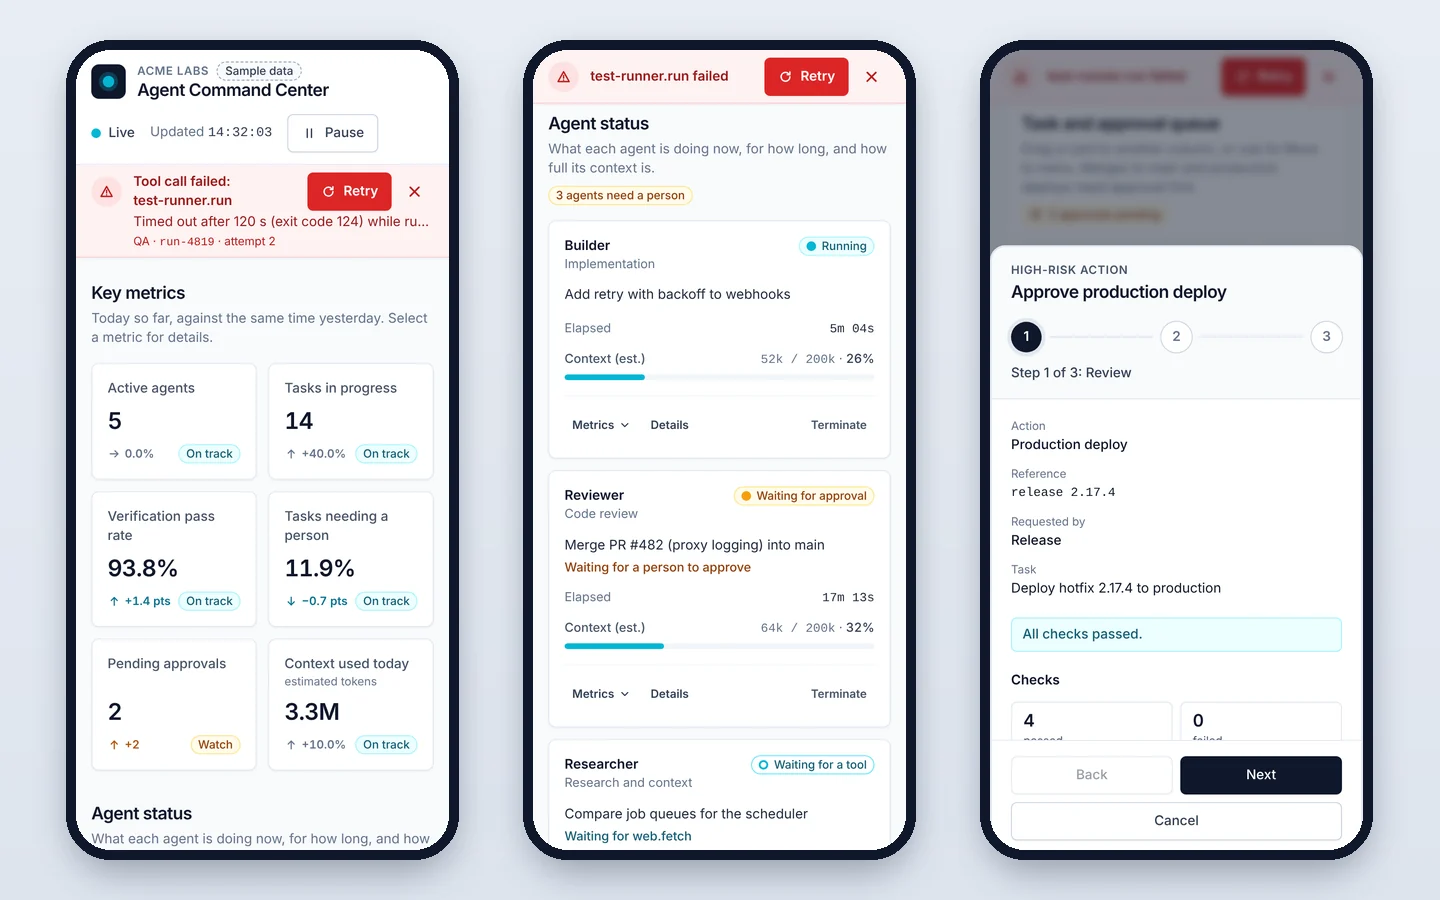
On a phone, the KPIs sit two to a row, the agent cards stack, the banner shrinks to a slim bar as you scroll, and approvals open as a sheet. Real screenshots at 390 px wide.
Swipe to see all three screens, or open the live demo on your phone →
The demo is the real build, running in your browser. Its simulated team works too: if T-136’s deploy and QA’s failed test run are still waiting after about 5 minutes, a team member approves the deploy and retries the test run, and the audit trail shows who. Some things to try:
Everything runs in your browser with fictional data. Nothing connects to real agents.
This is a real build, not a mock-up. Here’s exactly what we did.
dash-03 Minimalist KPI Card Grid with Trend Indicatorsdash-08 Server Monitoring Dashboard with Live Status Indicatorsdash-10 Project Management Kanban Board with Task Cardsdash-04 Activity Feed Timeline with Expandable Detailsdash-07 User Management Table with Inline Editing Capabilitiesint-02 Interactive Slide-Over Panel for Detailed Informationint-01 Glassmorphism Success Toast Notification with Progress Barint-04 Multi-Step Confirmation Modal with Warning Statesint-14 Delete Confirmation Modal with Text Input Verificationint-07 Interactive Error Message Banner with Retry ActionThis build: React 19, TypeScript 5.9 (strict), Tailwind CSS 3.4, Vite 6.4 and Vitest 2.1.
Your build will differ. Claude Code writes new code each run, so your layout, wording and test count won’t match ours. Our first build passed 288 tests, and our follow-up messages took it to 908. Plan to test your first build and ask for fixes, as we did.
This is the part of the build prompt we wrote ourselves: our notes, then the two output steps we rewrote. The rest is the Admin Dashboard build type’s prompt, filled in from our briefs and the final mission list.
What this dashboard is for:
- It's a command center for a team of AI coding agents (Builder, Reviewer, Researcher, QA, Docs and Release). People use it to see what each agent is doing, approve risky steps and catch failures.
- Live-status strip (dash-08): one card per agent instead of per server. States: running, waiting for a tool, waiting for approval, blocked, failed and idle. Show each agent's current objective, elapsed time and context use.
- Task and approval queue (dash-10): columns Queued, Running, Waiting, Needs review, Blocked and Done. Cards show the task, the owner agent and its age. Waiting cards say what they're waiting for: a tool, another agent or a human.
- Activity feed (dash-04): the audit trail. Each entry has a timestamp, the actor, the state change and an evidence reference.
- Agent roster table (dash-07): name, role, model, permission level and daily token budget, editable inline.
- Slide-over (int-02): agent or task details, with checks passed, failed, skipped and not run, plus recent events.
- Multi-step confirmation (int-04): approving a high-risk action, such as a merge to main or a production deploy.
- Typed-name confirmation (int-14): terminating an agent's run.
- Error banner with retry (int-07): a failed tool call.
- Simulate live updates on a timer, with a Pause button. All names and numbers are fictional; show a "Sample data" label.
- Make it look polished and professional, like a modern SaaS product, and make it work well on a phone.
Output steps 4 and 5, as we rewrote them. Step 4 lists the panels to wire into the app; we kept its opening words and replaced the list. The build type’s own step 5 makes a login screen the first screen.
4. … header + KPI grid + agent status strip + task and approval queue + activity feed + agent roster table + slide-over + toast + confirmation modals + error banner.
5. No login screen: the dashboard is the first screen.
We wrote this from the review agents’ reports on the first build. Claude Code made the changes in the build session.
Thanks. The build runs and every test passes. I tested it in a browser at 390, 768, 1280 and 1440 px, clicked every control and read all the text. Please fix the items below before I show it publicly.

The rules from my first message still apply: the same stack, the line limits, strict TypeScript and Tailwind only. For each behaviour fix, write a failing test first.

1. Queue layout
- At 1440 px the Done column is cut in half. At 1280 px, Blocked is cut off and Done is hidden. Make all six columns fit side by side from 1280 px up. Below that, sideways scrolling is fine, but snap to columns and show a fade on the right edge so people know there are more.
- Every task title is cut to one line. Let titles wrap to two lines.
- All six columns stretch to the height of the tallest one, which leaves big empty areas. Align columns to the top. Show the newest 5 cards in Done, with a "Show all" button.
- Replace the ← and → buttons on cards with a "Move to" menu that lists the other columns, so a card can go straight to any column. Today a reviewed task has to pass through Blocked to reach Done. Keep drag and drop. After a move, keep keyboard focus on that card's menu button in its new column.

2. Keep the board, the agent cards and the audit trail in step
- At load, Running holds 4 tasks, but only Builder is running, and Builder owns 3 of them. A task should be in Running only while its owner agent is working on it and showing it as its current objective. Fix the sample data and the simulation so that's always true.
- Approving the production deploy (T-136) puts it in Running while the Release agent still shows Blocked on another task. If the owner agent is busy, put the approved task back in Queued, marked as approved, so the agent picks it up next.
- Moving an agent's current task to Waiting by hand leaves the card with no reason and the agent still "Running". Give the card a reason ("Waiting for a person: moved here by you") and put the agent in a matching waiting state.
- Moving a queued task to Running leaves its owner idle. If the owner is idle, start it on the task. If the owner is busy, refuse the move with a short message.
- Moving an agent's current task back to Queued ends its run with no confirmation. Open the typed-name Terminate dialog instead, and log it as a termination.
- A task waiting for approval can be dragged to Queued, and the simulation then starts it without approval. Never start a task that has a pending approval.
- Dragging QA's failed task to Waiting clears the error banner while QA stays Failed. Only clear a failure when the agent actually recovers.
- Dismissing the error banner removes the only Retry button, and no new failure ever happens again. Add Retry to the failed agent's card and details panel, and let new simulated failures happen after a dismiss.
- Add tests for all of these. Extend the long-run simulation test so it mixes random user actions in with the ticks.

3. Sample data and simulation
- The checks in the details panel contradict the audit trail. Builder's T-142 shows "Unit tests: Not run" above the event "Check passed: Unit tests", and QA's T-139 shows "E2E smoke: Not run" above "Check failed: E2E smoke".
  - Give each seeded task its own list of checks, in pipeline order, to suit the type of task:
    - code: build, type check, lint, unit, integration, E2E
    - docs: links and spelling
    - research: sources cited
  - Never show a later stage passing when an earlier one failed or hasn't run.
  - Make the seeded audit trail match. T-139 should show the regression suite failing on the test-runner timeout, not a failed Build.
- The seeded story doesn't hold together:
  - The audit trail says Researcher started T-152, but Researcher's card shows T-145.
  - PR #482 (webhook retries) is waiting for merge approval while Builder is still building the webhook retries.
  - Make the seeded data tell one consistent story.
- After 10 to 30 minutes, the board repeats task titles (one appears 4 times), and tasks go to the wrong agents: Docs gets API work, and the read-only Researcher runs git.push.
  - Give each agent role its own pool of task titles, about 25 in all.
  - Never queue a title that's already on the board.
  - Only reassign a task between agents with the same role.
  - Keep the read-only Researcher off code changes and git.push.
- Release starts at "940k of 800k" tokens, already over its budget, with no warning, and long visits push other agents over too. Start every agent under its budget. Show an "Over budget" warning on the card and in the details when an agent goes over.
- Over a long visit, the "Context used today" change keeps climbing, because it's compared against a fixed "same time yesterday" number. Move the baselines forward with the simulation clock so the changes stay realistic.
- The sample model names "kestrel-4-…" match a real AI company and a published model. Rename them to clearly fictional IDs: acme-model-l, acme-model-m and acme-model-s.
- Ten of the twelve audit entries expand to "No further details recorded." Give every seeded entry a one-line detail, and hide the expand control on entries that have no details.
- Pausing freezes the clock. Everything done while paused gets the same time, and after resuming, the clock runs behind. Stamp a person's actions with the current time, and jump the clock to now on resume.
- Pause the live updates while the approval or terminate dialog is open, so a run can't end while someone is typing its name.

4. Layout and visual polish
- KPI cards:
  - At 1280 px, two cards spill their trend and badge below the card border.
  - At 1024 to 1279 px, the cards are huge.
  - Drop the fixed 3:2 card shape so cards fit their content, and line up the value and trend rows across each row.
- Roster and audit trail:
  - The roster's last column is cut off at 1280 px and on tablets. Make the roster fit without sideways scrolling: let the headers wrap and tighten the padding.
  - Put the audit trail beside the roster only when both fit. Below that, stack them.
  - The audit trail is 1,020 px tall next to a 440 px roster, which leaves a big empty block. Show the latest 6 entries with a "Show all" button, or let the trail scroll inside a panel the same height as the roster.
- The success toast appears top right, on top of the banner's Retry and Dismiss buttons and the header's Pause button. Move it to the bottom right on tablets and desktops.
- On phones the error banner is 156 px tall and stays stuck to the top of the page. Make it compact:
  - Retry and the X on the title row
  - the message on one line
  - a slim one-line bar once the page is scrolled
- On phones the approval modal opens scrolled past its title and step indicator, because focus goes to Cancel at the bottom.
  - When it opens, focus the title.
  - Keep the header and the buttons fixed and scroll only the body.
  - Keep the modal from jumping in size and position between steps.
- The permission dropdown in the roster is too narrow ("Operato…"), and opening it makes the table jump. Give it room.
- Blocked and Waiting for approval look the same, with the same amber dot. Give Blocked a different marker.
- Colour the audit-trail dots by outcome: red for failures, amber for approvals and blocks.
- The red Terminate button on every agent card competes with the real failure. Make it a neutral text button that turns red on hover. Keep red for the confirmation dialog.
- Opening Metrics on one agent card stretches the cards next to it. Stop that.
- Type sizes:
  - section titles 18 px
  - the agent cards' small lines 13 px
  - the Sample data chip 12 px
- On phones, keep model IDs on one line in the roster cards.
- The "High-risk action" label on the Confirm step is just under AA contrast. Darken it.

5. Keyboard and screen readers
- In the approval modal, after Next or Back, Shift+Tab escapes the dialog, and I was able to edit the roster behind it. Keep Tab and Shift+Tab inside open dialogs, and make the page behind them inert.
- After approving, terminating, retrying, dismissing or moving a card, focus falls to the page body. Move it to something that still exists: the task's card, the agent's card or the section heading.
- Announce the step to screen readers when it changes ("Step 2 of 3: Acknowledge").
- Set aria-controls on the Metrics and audit-trail toggles only while their panel is shown.

6. Wording
- "run run-4821" appears in the terminate dialog, the toast and the audit trail. Write "Builder's current run (run-4821)".
- "1 need a person" should read "1 agent needs a person" (and "3 agents need a person").
- Use "person" everywhere, not "human". On approval cards in Waiting, say "Waiting for a person: approval", like the other wait reasons.
- Mark agent-level token figures as estimates: "Context (est.)" and "Tokens today (est.)".
- Use American spelling ("Summarize") to match "Command Center".
- The Context KPI details show 4.3M → 4.8M as +10.3%. Use a baseline that rounds cleanly, so the numbers shown give the change shown.

7. Code
- Some JSX is packed onto very long lines (up to 422 characters), and that's how a few components stay under 50 lines. Add Prettier (printWidth 120) with a format:check script and format src. Then split any function that goes over 50 lines.
- Remove the unused MONO constant and the unused gauge icon.

When you're done, run the same final checks as before:
- the tests
- the line limits
- the build
- the browser check at phone and desktop widths, including 1280 and 1440 px

Then update BUILD_AUDIT.md.We wrote this from a second round of review agents’ reports, on the updated build. Claude Code made the changes in the build session.
Thanks, that's a big step up. The board, the agent cards and the audit trail now agree, the layout holds from 320 px up, and the keyboard and screen reader work is solid. I tested it again at widths from 320 to 1920 px, including phone sizes, and ran the simulation for an hour or more, once untouched and once while I approved and retried things as they came up. Please fix the items below before I show it publicly.

The rules from my first message still apply: the same stack, the line limits, strict TypeScript and Tailwind only. For each behaviour fix, write a failing test first.

1. Phone and focus
- On a phone (390 to 639 px), the error banner flickers and the page jumps back as soon as I scroll past the header. Turning into the slim bar makes the page 49 px shorter, so the browser pulls the page back above the 120 px point, the banner grows again, and it loops. A slow swipe can't get past it.
  - Switching between the full banner and the slim bar must not change the page's height.
  - Use two switch points: slim after about 160 px, full again only above about 60 px.
  - Add a browser test that scrolls slowly from 100 to 200 px at 390 px and checks that the banner switches once and the page isn't pulled back.
- In the roster, when I change a value and leave the field with Tab, Shift+Tab or a click elsewhere, focus jumps to the "Agent roster" heading. On a phone the page then jumps about 1,400 px up. Focus should stay where I put it, and the page shouldn't move.
- While the error banner shows, anything scrolled into view lands under it. After I approved T-136, the card and its focused Move to button were hidden behind the banner. Add top scroll padding the height of the banner (or the slim bar on phones), so focused and moved cards are always in view.
- If a task moves while its details panel is open (I approved it from the panel, or the live updates moved it), closing the panel drops focus to the page. Move focus to the task's card in its new column, or to the queue heading if it's gone. Don't let a card leave Done while its details panel is open.
- On a phone the toast sits on top of the approval and terminate sheets for 3 seconds and covers Cancel, so my tap hit the toast. While a dialog is open on a phone, show the toast at the top or not at all.
- Closing the toast with its X or Escape, or letting it time out while its X has focus, drops focus to the page. Send focus back to where it was before.
- With two failed agents, pressing Retry on the second while the first retry runs does nothing. Let each agent's retry run on its own.

2. The live story
- Release never leaves "Blocked: Waiting on the regression suite (T-139)". I retried, QA passed T-139 and it went to Done, but 30 minutes later Release and T-140 still said they were waiting on it. When a task that another task waits on reaches Needs review or Done, clear the block, log it ("Regression suite passed (T-139)") and resume the waiting task.
- I approved the 2.17.4 hotfix (T-136) and was told it "goes next", but it never went. It should ship before 2.18.0 anyway. A blocked agent isn't busy: when a task is approved while its owner is blocked, start it right away and leave the blocked task in Blocked. When the approved task is done, the owner goes back to the blocked one.
- Approvals come at the wrong time and name the wrong thing:
  - About 8 seconds after every load, Builder asks to merge PR #486 into main while T-142's integration and E2E tests haven't run. Reviewer asked after 1 of 6 checks. Only ask for a merge or deploy approval as the last step, once the task's checks have finished with none failed or not run. After approval, the agent merges or deploys and the task goes to Done, with no more checks and no review.
  - The reference comes from a counter, not from the task. "Review PR #493 (token budget alerts)" asked to merge PR #563, T-140 asked to deploy release 2.18.9, and a staging rollout asked for a production deploy. Take each approval's PR number or version from its task. Only merges to main and production deploys ask for approval. Number new PRs one at a time from #498, and log "Opened PR #498" before anyone is asked to merge it.
  - T-140, "Deploy release 2.18.0 to production", has no approval, so I could move it straight to Done. A merge or deploy task can't reach Done until it's approved, whoever moves it.
- "Waiting for another agent" only appears on the seeded T-154, and it ends by itself after 44 seconds, while Reviewer is still waiting for approval and never reviews anything. Make agent waits real: for example, after Builder opens a PR, it waits for Reviewer to review it, and the wait ends only when Reviewer finishes that review. Give Reviewer a queued "Review PR #484" task for T-154.
- Docs and Researcher redo the same few tasks every few minutes, and the earlier card vanishes from Done when its title is queued again. Never queue a title that's still on the board, Done included, and never delete a Done card to make room. Give each role 8 to 10 titles, and when a role runs out, leave its agent idle. Slow the work down so a task takes a few minutes and a review at least a minute.
- With nobody at the dashboard, 4 of 6 agents are stuck within a minute (two waiting for approval, QA failed, Release blocked) and stay stuck all visit. Have the team's people, the ones already in the audit trail, step in: after about 2 minutes, one of them approves a waiting request, retries a failed tool call or clears a person wait, logged under their name. Leave the seeded approvals and the seeded failure to the visitor for the first 5 minutes.
- In a long visit, Queued grows to 14 cards while Running and Needs review empty out, which brings back the big empty areas. Keep the simulated queue at about 4 to 8 tasks, and show the first 5 cards in Queued with a "Show all" button, like Done.
- Every agent except Researcher uses all seven tools, so the banner can say Docs failed a codegen.run call while writing a runbook. Give each role its own tools:
  - Builder and QA: all the code tools
  - Reviewer: repo.search, ci.pipeline and git.push
  - Docs: repo.search, web.fetch and git.push
  - Release: ci.pipeline, shell.exec and git.push
  - Researcher: web.fetch and repo.search
- Setting Builder to Read-only while it works on T-142 leaves it writing code. Refuse the change, with a short message, while an agent has code work running or queued.
- Moving an agent's current task to Needs review or Done ends its run without saying so. Say it in the toast and the audit trail ("Builder's current run (run-4821) ended: you moved T-142 to Done"). A failed agent's task can't go to Needs review or Done: say "Retry or dismiss QA's failed tool call first."
- Moving QA's queued T-150 to Running says "QA is busy with T-139" while QA's card says Failed. Say "QA's tool call failed on T-139. Retry it first, so T-150 stays in Queued."
- When Move to Done opens the approval flow, the toast after approving only says "Approved merge to main for T-137", and the card isn't in Done. Say where the card went and why.

3. Numbers
- Once I start approving and retrying, the token numbers run away again (items 3.4 and 3.5 last time). Each running agent burns 1.4M to 3.2M tokens an hour against daily budgets of 0.5M to 2M, while the "same time yesterday" baseline grows only 1.5M an hour for the whole team. After 30 minutes, 5 of 6 agents were "Over budget" and "Context used today" was over +60%, Critical. New tool failures came about once a minute, which pushed the person KPI to Critical too.
  - Lower the burn so the whole team uses about 1.5M tokens an hour with most agents busy, and keep the baseline in step.
  - Keep most agents under budget through a two-hour visit.
  - Make new tool failures rarer: about one every 5 minutes.
  - Add a test where a simulated person approves and retries every 20 seconds for an hour: the Context change stays within ±20%, at most one agent goes over budget, and no KPI turns Critical.
- Write the warning as "Over budget (est.): 500.3k of 500k tokens today", round "Tokens today (est.)" the same way in the details, and add "(est.)" to the "Compacted context" audit entry.
- Rename "Person intervention rate" to "Tasks needing a person".
- In a background tab the clock falls behind, then jumps on the next click. When the page becomes visible again, jump the clock to now, as Resume does.

4. Seeded data and wording
- At 1440 px the T-155 card is cut to "Regenerate the API client from the OpenA…", which reads like a real AI company. Rename it "Regenerate the API client from the spec".
- Most task titles are still cut at 1280 and 1440 px (20 of 26 at 1280). Shorten the titles to about 40 characters, keeping version numbers and PR targets.
- The seeded audit trail has gaps. T-137, T-139 and T-140 have no "Started" entries, QA's failure is "attempt 2" with no attempt 1, and check evidence numbers and run IDs run backwards in time. Fill the gaps and number them in time order. Seed Docs as idle for about a minute (it just sent T-134 for review), so its queued T-144 isn't waiting 28 minutes while Docs sits idle.
- On the agent card and in its details, "Waiting for a person: moved here by you" has nothing for "here" to refer to. Say "Waiting for a person: you moved its task to Waiting" there, and keep the task card's wording.

5. Layout
- The queue is cramped at 1280 to 1439 px, which includes 1366 px laptops. There:
  - let titles take three lines
  - tighten the panel and column padding
  - keep the owner and Move to on one row
  - keep "Review and approve" on one line
  After the title changes, check that no seeded title is cut at 1280 or 1440 px.
- Dropping a card in the empty space under a short column does nothing. Make each column's drop area run the full height of the board.
- On phones and tablets, a Move to menu near the bottom of the screen opens below the fold. Open it upward when there isn't room below it in the window.
- IDs break at their hyphens: "test-" / "runner.run" in the phone banner, "T-" / "139" in notes, "(run-" / "4821)" in toasts and "2.18.0-" / "rc.2" in objectives. Keep task IDs, run IDs, tool names and version numbers on one line.
- On narrow cards (QA's at 1024 px and below, most cards at 640 px), Terminate drops onto a line of its own, and the cards in a row end up different heights. Keep the actions on one row.
- Blocked has a square marker on the agent cards but a round dot in the queue's column header and in the Move to menu. Use the square everywhere.
- On phones the agent cards keep empty space under short objectives and notes. Reserve those heights only from 640 px up.
- The audit trail:
  - From 1024 to 1439 px it stretches the full width, and each expand chevron sits about 1,100 px from its text. Put it beside the roster from 1280 px, and put the chevron right after the text.
  - At 1440 px it's 141 px taller than the roster beside it. Make the two panels the same height.
- Approval steps 2 and 3 leave about 200 px of blank space. Repeat a compact summary of the action at the top of those steps: the action, the reference, who asked and the checks.
- The roster's budget error, "Enter a whole number of tokens, such as 1,200,000.", wraps to 4 lines and makes the row grow from 53 to about 120 px. Shorten it to "Whole number, e.g. 1,200,000" so the row keeps its height.
- On a 1920 px screen the page stretches edge to edge and the agent cards get very wide. Cap the content at about 1600 px and centre it.

6. Tests and BUILD_AUDIT.md
- In the long-run simulation test:
  - check the rules after every tick
  - let the simulated person also change permission and role
  - add rules: every task title comes from its owner's role pool, every approval's reference matches its task, approvals come only after the checks have finished, and no title is on the board twice (Done included)
- Add an App test that approves T-136 through the three steps and checks that Release starts it at once.
- Correct the Follow-up 1 section of BUILD_AUDIT.md:
  - 3.5 was measured with nobody acting
  - 5 of the 68 long lines are JSX or code
  - the bundle has four w3.org namespace URIs, not one
  - the long-run person only edits budget and model

When you're done, run the same final checks as before (the tests, the format check, the line limits, the build, the dev server, and the browser check, now at 320 to 1920 px). Then fast-forward the simulation an hour in the browser, once untouched and once approving and retrying as things come up, and check that the story and the numbers hold. Add a Follow-up 2 section to BUILD_AUDIT.md.We wrote this from a third round of review agents’ reports, after running the updated build for two hours three ways. Claude Code made the changes in the build session.
Thanks, this is very close. What I asked for last time holds up: the banner, focus, the moves, the numbers over two hours, and a story where blocks clear and approvals come last. I tested it again from 320 to 1920 px, ran it for two hours untouched and while approving and retrying, and tried a few other paths: pressing only Retry, terminating Release, and a long visit. A few things still show. Please fix these and I'll call it done.

The rules from my first message still apply: the same stack, the line limits, strict TypeScript and Tailwind only. For each behaviour fix, write a failing test first.

1. Laptops and phones
- At 1280 to about 1340 px, the roster beside the audit trail is too narrow. "Researcher" breaks into "Researche" and "r", every model ID is cut to "acme-model…", and editing a model shows "me-model-m". Keep agent names and model IDs whole, on one line, at every width, with the rows at their normal height. Let Role wrap, or rebalance the columns.
- After I approve T-136 or move a card, the page scrolls only far enough to show the card's Move to button, and its ID and title stay under the banner. At 1440 px, all I can see is "Production deploy approved / Release / Move to". Scroll the whole card into view below the banner, then focus it without scrolling again. Add a browser check at 390 and 1440 px.
- "PR #484" splits across two lines in T-154's wait note, and "PR #482" does at 1280 px. Keep PR numbers on one line, like the other IDs.
- Once I scroll on a phone, the slim banner cuts the tool name to "Tool call failed: test-ru…". Keep the tool name whole, for example "test-runner.run failed".
- When a failed agent's card is narrower than about 270 px (QA's card at 320 px and around 640 px), Details and Terminate turn into icons with no labels. Researcher's role is also cut to "Research and c…". Keep the labels (put Retry on its own row if you need to), and let the role wrap.
- On a phone, a failed agent's details panel puts Retry about 1,000 px down, after the checks and events, and the top of the panel doesn't show the error. Put the error message and Retry right under the status line.

2. Approvals and checks
- The first approval most people will open, T-137, says "Not every check ran." in amber on every step, while the audit trail says every check finished. Its only check that didn't pass was skipped. Count a skipped check as finished: say "All checks finished (1 skipped)." and keep "Not every check ran." for checks that haven't run.
- In two hours, 4 of 14 code reviews failed their own checks, ran them again with no fix in between, and still ended "No changes requested". When a review's checks fail, have Reviewer request changes and send the PR back to Builder, then review it again after Builder's fix. Before a failed check runs again, on any task, log the fix ("Pushed a fix for Unit tests"). Log "No changes requested" only when every check passed.
- Release's operations tasks run the code checks. "Rotate the staging database credentials" and "Renew the TLS certificates on staging" show Build through E2E, and the trail says "Check failed: Build" on a credential rotation. Give operations tasks their own short checks, such as Dry run, Config check, Smoke test and Rollback plan, and treat "Update the release checklist" as a docs task. Keep Build through E2E for code changes, reviews and merges.

3. The release story
- The 2.17.4 hotfix still doesn't always ship before 2.18.0. If I press only Retry at load and wait, 2.18.0 is deployed at about 8 minutes and 2.17.4 at about 9½, which rolls production back to an older version. Make T-140 wait for the hotfix as well as the regression suite, and have its note say what it's still waiting for. Release mustn't ask to deploy 2.18.0 until 2.17.4 is deployed.
- Terminating Release's run while it's blocked, or moving T-140 to Queued (which asks for the same thing), drops T-140's wait on T-139. Release then deployed 2.18.0 at 4 minutes while the regression suite was still failing.
  - A move or a terminate must never skip a wait on another task. The waiting task stays in Blocked until what it waits on reaches Needs review or Done.
  - Refuse a move out of Blocked with a short message, for example "T-140 waits on the regression suite (T-139). Retry QA's failed tool call first."
  - Never start a task while one of its waits is open.
- If I set Reviewer to Read-only while it has nothing running, the roster accepts it. After that, every new review and merge is queued for Reviewer for good, so Builder's PRs never move. Count reviews and merges as code work for the Read-only rule. While Reviewer is read-only, hold Builder's PRs with a note that says why.

4. A long visit
- Done still keeps only its newest 10 cards. The oldest vanish 1½ to 2 minutes after load, one of them 20 seconds after I closed its details panel, and once a card is gone its title comes back. About 70 minutes in, Docs redid "Document the retry policy for tools".
  - Keep every Done card. Done already shows 5, with Show all.
  - Never queue a title that's already been used in this visit.
  - Ten titles per role run out in about an hour, so give each role about 20.
  - When a role does run out, leave its agent idle.
- The KPIs:
  - Idle agents wait 20 to 50 seconds before they start queued work. On some timelines several agents are idle at once while work waits, and Active agents turns Critical. Have an idle agent start its next queued task within a few seconds.
  - The "same time yesterday" values for Active agents, Tasks in progress and Pending approvals are far from what the team usually shows, so the cards read +100%, −57% and −100% side by side. Set them near the team's usual level during a visit, so the changes stay within about ±40%.
  - The numbers tests use only 4 seeds. Run the two-hour untouched check and my one-hour approve-and-retry check over at least 50 seeds. No KPI may turn Critical, and at most one agent may go over budget.

5. Seeded data and wording
- The seeded audit trail still has gaps:
  - T-136 and T-154 have no "Started" entry.
  - T-133, T-138, T-151 and T-153 are in Needs review with no "Sent for review" entry, and their details say "No recent events." Seed those entries at times when their owners weren't busy with another task. Right now T-151 and T-153 reach Needs review while QA and Release are already on T-139 and T-140.
  - None of the queued cards has a "Queued" entry, except T-137 and T-156.
  - PR #482 "passed review", but there's no review. Add the finished review task and its entry.
  Keep every number in time order.
- Most of the people who step in never appear in the seeded trail; only Diego Alvarez does. Give the rest of the team earlier entries in the seeded trail, or use only people who are already there.
- When a team member clears a wait or unblocks a card, the entry reuses the card's note. For example, Sam Okafor's "Cleared the wait on T-142" has the detail "Moved here by you: done." Write these in plain words that say who did what, for example "You moved T-142 to Waiting; Sam Okafor sent it back to Builder."

6. Tests and BUILD_AUDIT.md
- In the long-run test, run at least 50 seeds and add these rules:
  - no task ever leaves the board
  - no title is queued twice
  - no task starts while a wait is open
  - 2.17.4 deploys before 2.18.0
- Add two App tests:
  - one presses only Retry at load and checks that 2.17.4 deploys before 2.18.0
  - one terminates Release at load and checks that T-140 stays blocked until T-139 passes
- In the Follow-up 2 section of BUILD_AUDIT.md, add two things it leaves out: a move or a terminate dropped a task's wait, and the numbers tests used 4 seeds. Then add a Follow-up 3 section.

When you're done, run the same final checks as last time: the tests, the format check, the line limits, the build, the dev server, and the browser check at 320 to 1920 px. Then fast-forward the simulation two hours in the browser, three ways: untouched, approving and retrying as things come up, and pressing only Retry at load. Check that the story and the numbers hold.
The Admin Dashboard build type, the four brief templates and all ten missions come with the vault. Our notes and follow-ups are above. Our finished code isn’t included: you build your own.
Get the Mission Vault: $97It’s a front end running on simulated data, with no back end. In your own build, you connect your data and back end.
The product behind this example
The steps we followed, for your own dashboard:
Claude Code builds your own React and TypeScript dashboard project on your machine, set up with Vite and Tailwind CSS and tested with Vitest. Every build type uses this stack.
AI Dashboard Mission Vault
$97
The product that built this example. It doesn’t include this example’s code: you build your own.
One-time payment. Instant download from Gumroad. Commercial-use license: use what you build in your own or client projects. All sales are final, per the Gumroad listing.
What you need: Claude Code, Node.js 22 or newer, and your own Claude account or API key. Builds use your own Claude usage. The vault is a folder of Markdown files, made for Obsidian (free).
Prefer copy-paste prompts instead of Claude Code missions? See the prompt packs →
An agent dashboard is for the people supervising the work. It should make automated work easy to inspect, not make it look finished.
See what automated work is changing across projects: objectives, task state, checks and approvals.
Keep bounded workflows moving: queue state, context pressure, tool failures, retries and handoffs.
Decide whether work can go ahead from evidence: check results, open findings and links to the output.
How many tasks are queued, running, waiting, in review, blocked or done, with each task’s age and owner. Keep failed and blocked work visible until it’s resolved.
In the demothe six-column queue.
Checks that passed, out of the checks that ran. Show passed, failed, skipped and not run, not just one percentage.
In the demothe checks in each task’s details.
The share of tasks where a person had to approve, retry, unblock or stop an agent, counting each task once. Show the reasons too: a deliberate safety gate isn’t a failure.
In the demothe KPI card of the same name, and the approval queue.
Estimated tokens, tool calls, elapsed time and context use per run. Label estimates as estimates. They aren’t billing data.
In the demoeach agent’s context meter.
Each agent’s state, objective, elapsed time and context use, in one quick scan.
The main area: queued, running, waiting, review, blocked and done work, each with an owner.
A side panel for checks, recent events and links to evidence, without losing your place.
Failures, approvals, permission requests and every state change, with who made it.
Keep exploring